
For a real estate platform, a new market can introduce different source systems, property attributes, identifiers, business rules, geographic structures, and reporting requirements, each of which enters the platform somewhere.
The engineering question is where those differences land in the existing platform, and whether the current data model, integrations, search, workflows, and analytics can absorb them without a second architecture forming alongside the first. Connecting the feed is one part of the problem. In many multi-market projects, the harder work comes afterward, in fitting the new data into the model, workflows, search, and reporting a platform already runs.
For ORIL, this kind of work often starts by assessing the existing real estate data integration layer and identifying where a new market would connect to it.
Why Entering a New Real Estate Market Is a Data and Architecture Problem
The United States has no national listing database. RESO tracks 484 MLS systems in the U.S. as of August 2026, and entering a new market usually requires integrating at least one more of them, along with the local systems around it.
Many of those MLSs share RESO standards, but several things can still vary by source:
- Access arrangements and entitlements
- Supported data elements and identifiers
- Update behavior and refresh frequency
- Local business rules
A platform’s existing integrations, search logic, and data model carry assumptions from the markets already live, for example:
- Which fields exist
- How status codes work
- How addresses are structured
- What a “property” record contains
Those assumptions often fail quietly when a new market introduces fields that do not map cleanly or values the model has no place for.
Uncleaned regional feeds also compound over time. Ingesting them without normalization and validation adds PropTech data debt that surfaces later in search, analytics, and reporting.
The real difficulty is architectural: representing another market’s data inside a platform that already works, without destabilizing what is in production. Where the underlying business concepts are still shared, the existing integration and data-model layers can absorb the new market. A separate, market-specific path is worth introducing only where the requirements differ in substance.
What Changes When Your Real Estate Platform Enters a New Market?
When a platform enters a new market, the differences usually show up in four areas: source systems, operational systems, data semantics, and reporting. Those differences land in different parts of the stack: ingestion, data modeling, search, workflows, and analytics.
MLS and Local Listing Sources
Different markets are served by different MLS organizations and listing providers, and their API or access models, available fields, identifiers, and update frequencies can vary. Two sources serving different markets can represent the same concept, such as listing status or property type, using different values or business rules. Reconciling those differences at the source is where MLS data normalization work begins, before any of it reaches the product.
Delivery and access models vary as much as the data:
- Modern MLS integrations commonly use the RESO Web API.
- Some legacy systems may still expose RETS or scheduled exports, even though RESO has deprecated RETS in favor of the Web API.
- Third-party aggregators add their own coverage, latency, and licensing terms.
Access itself is not always trivial either. Entitlement, certification, and feed reliability vary by source. Comparing candidate providers for a region is easier with a structured real estate APIs benchmark than by evaluating each feed in isolation.
CRM and PMS Configurations
Market expansion reaches beyond listing feeds into the operational systems a platform depends on. A new region may also introduce a new CRM or PMS instance, different workflows, distinct entity relationships, and field mappings that do not match the ones already in production.
These systems often carry their own market-specific logic:
- Lead routing
- Ownership records
- Lease or transaction states
Regional Data Standards, Property Attributes, and Geography
The modeling problems become more significant when two markets use different meanings, enumerations, or structures for concepts the platform currently treats as universal. Property types, local attributes, units of measurement, address structures, and geographic hierarchies can all differ, and some local concepts have no equivalent in the current schema.
| Local-market source | Typical canonical treatment |
| Region-specific property types and status values | Standardized enumerations, with local values kept as metadata |
| Lot or floor area in mixed units (sq ft, sq m, acres) | A canonical unit for calculations, with the source value and unit retained for traceability |
| Address and postal formats that vary by region | A normalized address model plus geographic identifiers |
| Local parcel or listing identifiers | Resolve to canonical entities while retaining source-system identifiers for traceability. |
One core design decision is how to preserve locally meaningful information while still mapping it into shared entities, which matters for any property listing platform development that spans more than one market.
Reporting Requirements and Cross-Market Metrics
Differences in the source data propagate into analytics. A metric defined one way in an existing market can carry a different definition, currency, or cadence in a new one.
“Active listings,” for instance, may depend on source-specific status values, while revenue or transaction metrics may follow different currency or date conventions. Left unaligned, one KPI label can represent two different calculations across regions.
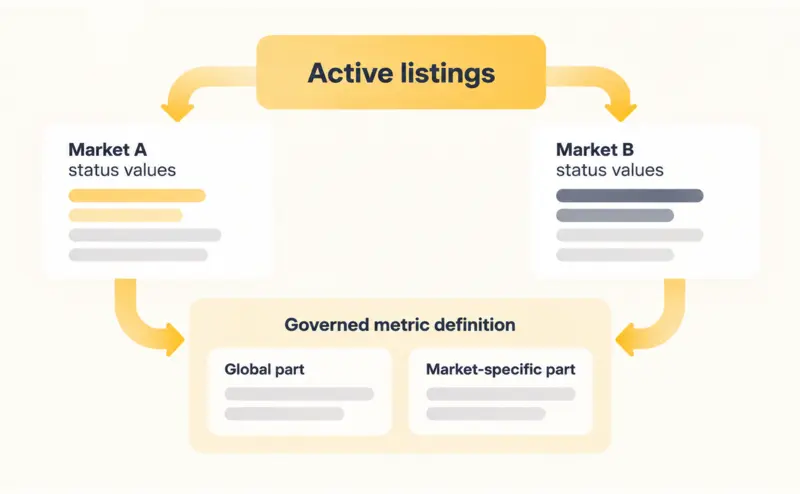
Cross-market comparability depends on defining which parts of a metric are global and which stay market-specific, and on tracking data lineage from source to dashboard. Without that alignment, connecting a new market into existing real estate data visualization can leave teams maintaining parallel dashboards or metric definitions that are difficult to reconcile.
The Pre-Launch Data and Integration Checklist
These differences map onto a practical assessment, best run while the design is still open. For each step, the useful output is a decision, not only a description.
| Step | Inspect | What can break | Decision |
| 1. Audit the existing platform and data model | Canonical entities, relationships, source integrations, APIs, and search or listing workflows, plus market assumptions sitting in application code | A field or enumeration treated as universal may not exist, or may not mean the same thing, in the new market | Which assumptions belong in the shared model, and which need configuration or an extension point |
| 2. Map the new market’s data sources and dependencies | MLS and listing sources, CRM and PMS instances, geographic and enrichment providers, and reporting sources, with each one’s access, authentication, and update frequency | An incomplete inventory can leave dependencies undiscovered until implementation has started, creating rework that could have been caught earlier | Which sources are in scope for launch, and which can follow later |
| 3. Identify schema, attribute, and business-rule differences | Field names, types, enumerations, required versus optional data, identifiers, and business rules | Concepts that are missing, incompatible, or meaningful only locally will not map cleanly | How each difference is represented, and which parts of the model need to change |
| 4. Decide what to standardize and what to keep market-specific | Each field’s role: whether it supports a shared product or reporting requirement, or is meaningful only locally | Over-standardizing destroys information that only makes sense in one region, and over-localizing fragments the model | Which fields join the shared canonical model, and which become market-specific extensions or metadata |
| 5. Determine whether the data model can absorb the market | For each difference, the smallest change that supports it (a new value, attribute, entity, or relationship), traced through APIs, search, workflows, and analytics | Search often shows the mismatch first: a type, status, or range that maps differently returns incomplete results even when ingestion succeeds | Extend through existing entities and extension points, or if core entities have to change structurally, revisit the model before implementation |
How to Integrate a New Market Without Fragmenting the Platform
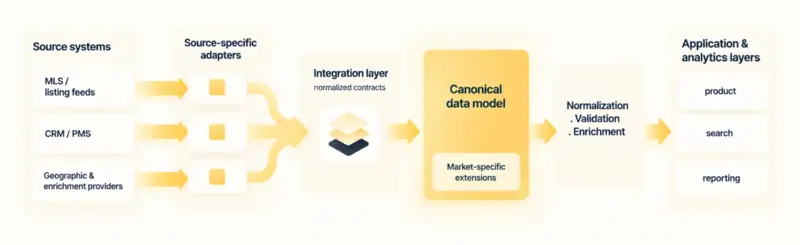
One common way to scale multi-market integrations is to isolate source-specific complexity near the ingestion boundary while keeping shared business concepts in a canonical model. The exact boundaries depend on the platform’s existing architecture and the differences the new market introduces. The exact sequence should be adapted to the organization’s existing architecture and integration constraints.
Source-Specific Adapters and the Integration Layer
Source-specific adapters, or connector modules, sit at the ingestion boundary and isolate the vendor-specific parts of each source from the rest of the platform:
- Authentication and access
- Source-specific transformation
- Vendor quirks in fields and values
Whether adapters split per source, per protocol, or per provider family depends on how the sources differ and how the existing integration layer is structured.
The integration layer above them can expose normalized contracts to downstream services, keeping source-specific structures from leaking unnecessarily into application logic.
Canonical Data Model and Market-Specific Extensions
At the center of the design sit the stable business entities and semantics shared across markets. New markets attach through extensions rather than by reshaping that core:
- Added enumerations
- Optional attributes
- Local metadata linked to shared entities
A useful architectural rule is to avoid making a vendor’s schema the application’s domain model. The integration layer absorbs provider-specific structures where practical, while the canonical model represents the business concepts the product needs.
For example, a platform might model property_type as a fixed enumeration, and a new market might introduce a locally meaningful subtype. The team doesn’t need to replace the enumeration. It can keep the shared property type for cross-market use and store the local subtype as an extension, provided search and reporting handle it explicitly.
Normalization, Validation, and Enrichment
As data moves through the integration pipeline, several distinct processing steps may be applied:
- Normalization brings structurally or semantically different source data into a shared representation.
- Standardization decides which concepts are represented consistently across markets.
- Validation checks types, ranges, and required fields against expected constraints.
- Identity resolution determines whether records represent the same underlying entity.
- Enrichment adds attributes not present in the source.
Identity resolution is separate from field mapping. The same underlying property may be represented by a source listing identifier, a parcel or other property identifier, and an internal platform entity ID. These identifiers have different scopes and should remain traceable to their source systems.
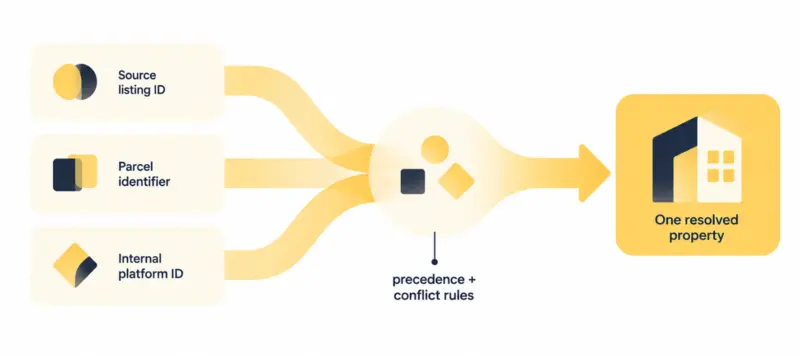
Enrichment can then add the geographic, parcel, tax, or demographic attributes that specific product and analytics use cases need. This kind of property data enrichment complements normalization rather than replacing it. All of these steps need monitoring, error handling, and a plan for schema and source changes over time.
Connecting the New Market to Product and Reporting
A feed connection is one milestone. Integration is complete when the new market’s data behaves correctly across the surfaces that already serve the platform: APIs, search, workflows, listings, and reporting. The aim is for the new market to use the same core product capabilities, while accommodating any market-specific behavior that is required.
The same pattern applies whenever a platform builds on an external property or financial dataset: the data is integrated and modeled once through a shared layer, which keeps the surrounding architecture simpler as more products depend on it. A new market is a version of the same problem.
Where the underlying metric definitions are shared, reporting can span markets from the same model, while markets that differ in regulation or business model keep their own views.
What Does “Launch-Ready” Mean for a New Market?
From a data and architecture perspective, a market is launch-ready when its required data can move through the platform without unresolved schema gaps, duplicated models, or unmanaged market-specific logic. That technical readiness sits alongside the project’s operational, access, compliance, and product requirements. The data-and-architecture conditions usually include:
- Critical sources connected, with authentication and access confirmed.
- Source-to-canonical mappings validated against real records.
- The data model has a defined representation for every required market concept.
- Normalization, validation, identity resolution, and duplicate-handling rules tested on sample data.
- Data quality and freshness monitored, with error handling in place.
- Product workflows and search verified against the new market’s data.
- Reporting consistent with governed metric definitions across markets.
How ORIL Helps Real Estate Platforms Expand Into New Markets
The engineering spans the existing platform and the new-market integration together, rather than as separate projects: auditing the current data model, designing source-specific integrations, extending entities and APIs, implementing normalization and enrichment, and validating the new market through search, workflows, and analytics.
Handled this way, the integration and data-model foundation built for one additional market can provide reusable patterns for later expansion, reducing the need to redesign the architecture for every new market. That kind of multi-market foundation work is what a PropTech technology partner focused on real estate takes on.
Planning a New-Market Launch?
The most useful moment for this work is before the first feed is connected, while the data-model and integration decisions are still open and cheap to change. A short assessment of the existing platform can surface the integration and data-model risks a new market introduces, and outline an expansion architecture that later markets reuse.


